Contents
- Why Germany Is the Right Test Case for Predictive Economics
- What Predictive Economics Actually Measures
- From Credentials to Proof: How Objective Performance Changes the Game
- How German Industry Could Turn Trust Into a Quantifiable Asset
- Could Germany Be the First Nation to Treat Credibility as Infrastructure?
Predictive economics proposes that credibility can be engineered like any other industrial standard—measured, certified, and audited rather than merely asserted. Germany is the natural test case: a nation that turned precision and accountability into an economic identity now faces the same institutional trust decline eroding confidence worldwide. If judgment and intelligence can be scored objectively, the country that perfected the DIN standard may be positioned to define the standard for trust itself. The question is whether German industry and policymakers will treat credibility as infrastructure—or leave the measurement of reputation to others.
Why Germany Is the Right Test Case for Predictive Economics
Consider a German machine tool, a mid-sized engine component, or a DIN standard for a fastening bolt. Each is designed to be inspected, toleranced, and certified before it is trusted in the field. Germany did not build one of the world’s strongest industrial economies on charisma or reputation alone. It built it on standards, accountability, and engineering rigor — a culture in which claims are tested and the test results are visible. Predictive economics asks a deceptively simple question: if a bolt can be certified, why not a judgment? If a production line can be audited, why not a forecast or the credibility of the person making it? The premise is that credibility can be engineered like any other standard, and Germany is the natural place to test that premise.
That proposition lands against a difficult backdrop. Institutions worldwide are losing public trust. The OECD’s long-running work on trust in public institutions has repeatedly found that confidence in government and many public bodies is uneven, fragile, and unevenly distributed across income and age groups, even in wealthy democracies. Germany is no exception. Surveys such as the Edelman Trust Barometer have documented similar strain across media, government, and business. Meanwhile, the gap between what people are told and what can be verified has widened, from the pandemic years to debates over energy policy, migration, and defense spending. Predictive economics enters this gap not with a slogan but with an engineering question: can credibility be measured, scored, and maintained to a standard?
Germany’s answer is not obvious, which is precisely why the test is useful. The country’s industrial credibility rests on institutions that do not depend on individual promises: the DIN standards system, the TÜV inspection and certification regime, the dual vocational training model, and the Industrie 4.0 agenda for connected manufacturing. These are systems for making claims checkable. They are not perfect, and they are slow. But they share a logic that predictive economics borrows directly: define the specification, design the test, record the result, publish the record, and let the record outlive the individual. The question the article pursues is whether that same logic can be extended from products and processes to people, forecasts, and public decisions.
The sections that follow take that question apart. First, what predictive economics actually measures — what it means to score intelligence, judgment, and credibility objectively rather than through titles, pedigree, or tenure. Second, how objective performance might outperform traditional credentials in hiring, investing, and public trust, and what evidence would be required before anyone should believe that claim. Third, a practical roadmap for how German industry and policymakers could turn trust into a quantifiable asset through standards, certification bodies, pilot programs, and audit mechanisms. And finally, the question that frames the whole investigation: could Germany become the first nation to treat credibility as infrastructure — not as a cultural virtue or a marketing phrase, but as something designed, maintained, inspected, and repaired like a bridge or a power grid? Each section builds on the last, so the payoff of the definition that follows depends on the tension set up here.
The core questions this investigation answers
Is there a measurable way to score intelligence and judgment? Can objective performance outperform traditional credentials? How might German industry respond to predictive economics? And what happens when trust becomes a quantifiable asset? The final question is the boldest: could Germany become the first nation to treat credibility as infrastructure?
There is a reason to take the German test case seriously rather than treat it as a thought experiment. Nations that already run certification cultures have a shorter distance to travel. Germany has regulators, testing houses, trade bodies, and chambers of commerce that already know how to write a specification and audit against it. It has a public that largely accepts inspection as a normal cost of doing business. What it has lacked is a standard for the thing those systems quietly depend on: the credibility of the people and predictions that make decisions inside them. If predictive economics is to be tested anywhere at national scale, a country whose identity is bound up with measurable standards is the logical first site. The next section turns to what such a standard would actually have to measure.
What Predictive Economics Actually Measures
Strip away the jargon and predictive economics asks a simple question: how often is a person, team, or institution right about the future, and can that accuracy be measured, compared, and audited? It treats forecasts, estimates, and judgments as data points rather than opinions. The output is a track record — a public, verifiable record of prediction accuracy — instead of a résumé line. In that sense it applies the same discipline German industry already applies to tolerances and stress tests: define the metric, measure it repeatedly, and publish the result.
This is a meaningful shift from how credibility is usually assigned. Today, reputation is largely subjective: who went to which university, who was quoted in which publication, who sits on which board. Predictive economics replaces those proxies with a continuous score built from resolved forecasts — claims that have already proven right or wrong. The unit of measurement is not prestige but calibration: did a stated 70 percent confidence level translate into roughly seven correct outcomes out of ten? That question is answerable, and it is answerable without knowing a person’s background.
Three Things a Predictive Score Can Capture
- Calibration — whether stated confidence levels match observed outcomes over many forecasts, which is measurable in a way that general intelligence claims are not.
- Resolution — whether a forecaster can distinguish likely from unlikely events, rather than clustering every prediction near 50 percent to avoid being wrong.
- Consistency over time — whether accuracy holds across domains and periods, which separates durable judgment from a lucky streak.
Measuring judgment and intelligence this way is deliberately narrow. A predictive score does not claim to capture creativity, character, or leadership. It captures one specific capacity: forming a view about an uncertain future and being accountable for it. That narrowness is a feature, not a flaw. Narrow, well-defined metrics are exactly what made German industrial standards exportable — a screw thread specification is useful precisely because it does not try to describe the entire machine. A credibility metric earns trust the same way: by doing one thing precisely and reproducibly.
Here is a practical example of a judgment-scoring model. Imagine a procurement analyst who forecasts supply disruptions. Each quarter she logs predictions with confidence levels: a 60 percent chance a supplier misses a delivery window, an 80 percent chance a price index rises. When outcomes resolve, her score updates. Over two years, her stated 80 percent predictions come true 78 percent of the time, and her stated 60 percent predictions come true 58 percent of the time. That is well-calibrated judgment, evidenced. A colleague with a more impressive title but unmeasured forecasts has no equivalent evidence, however senior he is.
The obvious objections deserve a direct answer. First, fairness: scoring could simply encode new biases, especially if early datasets favor those already inside the system. The counter is transparency — open methodology, auditable outcomes, and the ability to challenge a score. Second, reductionism: a number cannot capture a whole person. True, and it should not try. A credibility score is one input among many, like a credit rating is for a company, not a verdict on its worth. Third, gaming: people will optimize for the metric. That risk is real, which is why the metric must reward calibration on questions the forecaster cannot choose after the fact.
The Core Distinction
Traditional credentials ask where someone learned. Predictive economics asks what they got right, how confident they were, and whether that confidence held up. One is a proxy for judgment. The other is evidence of it.
What the Measurement Requires
- Resolvable questions — every forecast must have a clear, objective resolution criterion and a deadline, so scoring cannot drift into interpretation.
- Sealed records — predictions must be logged before outcomes are known, preventing retrospective editing of one’s own track record.
- Public methodology — the scoring formula, sample sizes, and confidence intervals should be open to inspection and independent audit.
- Domain context — scores should be reported per domain, since accuracy in commodity pricing says little about accuracy in energy policy.
What emerges is not a single number that ranks human worth but a portfolio of evidence. Over time, that portfolio becomes comparable across people, teams, and institutions in a way that credentials never were. A mid-sized manufacturer in Baden-Württemberg could compare a supplier’s delivery forecasts against outcomes the same way it compares material certificates. The comparison is not perfect, but it is objective, repeatable, and improvable — which is the standard German industry has always held itself to.
This is where predictive economics connects to the broader argument. If judgment can be scored, then trust no longer has to rest entirely on institutional reputation, which is precisely the resource now under strain. It can rest, at least partly, on demonstrated accuracy. The question is no longer whether this is conceptually possible — calibration scoring is a well-established forecasting method — but whether an economy is willing to build the institutional scaffolding around it. The next section turns to the evidence that objective performance can outperform credentials in practice.
From Credentials to Proof: How Objective Performance Changes the Game
Germany’s economy runs on signals. A Meisterbrief, a TÜV certificate, a Duale Ausbildung record — each compresses years of effort into a single artifact that markets can trust without inspecting the underlying work. Credentials are, in effect, the original reputation infrastructure: standardized, portable, and broadly legible. The problem is that they measure inputs — attendance, completion, affiliation — far more reliably than they measure outputs. A diploma confirms that someone sat in the right rooms for the right number of years. It says much less about whether their judgment holds up when the situation is novel and the stakes are real.
Predictive economics proposes a shift from proxy to proof. Instead of asking what a person has been certified to know, it asks what their track record says about what they will get right next. This is not a radical idea imported from Silicon Valley; it is how several mature domains already operate. Actuaries have priced risk from observed outcomes for centuries, and their models are audited, regulated, and trusted by insurers and supervisors. Elite sport has moved almost entirely to predictive performance metrics: expected goals, player-tracking data, and workload models now shape transfer decisions worth tens of millions of euros. In both cases, the shift happened because the measured signal proved more predictive than the inherited proxy. The open question is whether the same logic can be extended to judgment, credibility, and professional competence — and what evidence would be required before German institutions accept it.
The contrast is sharpest in hiring. A credential-based process screens on titles, grades, and institutional pedigree, then interviews for cultural fit — a sequence with well-documented weaknesses. Research on structured versus unstructured interviews has long shown that unstructured judgment introduces noise and bias, while structured, scored assessment correlates far better with later job performance. A performance-based process inverts the flow: it begins with evidence of what a candidate has actually produced and predicted, then uses the credential only as context. In practice this might mean weighting documented forecasting accuracy, code review outcomes, or project post-mortems over a GPA. The persuasive claim is not that credentials are worthless — they carry real information about persistence and baseline knowledge — but that they are an expensive and imprecise substitute for outcome data that now exists in abundance.
| Dimension | Credential-based system | Performance-based system |
|---|---|---|
| What is measured | Inputs: degrees, certificates, tenure | Outputs: observed results, forecasts, decisions |
| Signal timing | Before performance, at entry | Continuously, from track record |
| Granularity | Coarse; institution-level averages | Fine; individual and task-specific |
| Susceptibility to gaming | Brand inflation, degree mills | Selective reporting, survivorship bias |
| Auditability | Accreditation of institutions | Scoring methodology and data lineage |
| Maturity in Germany | Deeply institutionalized | Emerging in sport, insurance, some HR |
Where objective scoring already works, the mechanics are instructive. Actuarial models succeed because outcomes are recorded consistently, the time horizon is defined, and errors are eventually observable — a claim either pays out or it does not. Sports analytics succeed for similar reasons: the pitch is a controlled measurement environment with complete event logs. Both domains also share a discipline that predictive economics must borrow: they distinguish sharply between calibration (are stated probabilities honest?) and discrimination (can the model separate good from bad?). A credibility score that is well calibrated but weakly discriminating is still useful; one that discriminates sharply but is overconfident is dangerous. Any serious proposal to score judgment must report both, publicly and against held-out data.
Where objective scoring still fails, the failures are predictable and worth naming honestly. Judgment in complex professional settings unfolds over long horizons with confounding variables, so attribution is genuinely hard — a good decision can produce a bad outcome and vice versa. Selection effects corrupt the data: if only confident people opt into scored systems, the sample is biased from the start. Goodhart’s law applies with full force; once a metric becomes a target, participants optimize the measure rather than the underlying competence. And there are legitimate concerns about privacy, surveillance, and the reduction of human capability to a number. German audiences, shaped by strong data-protection norms, will and should interrogate these points. The honest position is that performance scoring is a complement to credentials under defined conditions, not a wholesale replacement — and that those conditions (complete outcome data, disclosed methodology, independent audit) are exactly the kind of engineering discipline Germany already knows how to build.
What evidence would prove the case
A credible claim that objective performance beats credentials requires more than anecdotes. The minimum evidentiary standard: (1) prospective, pre-registered pilot studies comparing scored and credential-based decisions on the same population; (2) reported calibration and discrimination metrics against held-out outcomes; (3) independent audit of the scoring methodology and its data lineage; (4) replication across at least two sectors before any national claim is made. Editor’s note: specific effect sizes should be verified against published studies before citation in final copy.
For German industry, the strategic implication is not to abandon credentials but to layer proof on top of them. A certification body could issue a verified performance record the way TÜV issues a safety mark: not a verdict on a person’s worth, but an audited statement about what their track record predicts. The first movers are likely to be domains with clean outcome data and high cost of misjudgment — underwriting, procurement, engineering project delivery, and clinical decision support. In each, the sequence is the same: instrument the outcome, publish the method, submit to audit, and let the score earn trust the way any German standard does — slowly, then completely. The transition from credentials to proof will not be a rupture. It will be a certification process, and that is precisely why it has a chance of working here.
How German Industry Could Turn Trust Into a Quantifiable Asset
The previous sections established that predictive economics is only as credible as the infrastructure that produces and verifies its scores. This is where Germany holds a structural advantage that few other nations can replicate. The country did not become an export leader by publishing good intentions; it built a dense apparatus of norms, testing houses, and independent auditors that make «Made in Germany» a claim a buyer can verify. The practical question is therefore not whether Germany can invent scoring methodologies — many actors already claim to — but whether it can institutionalize them with the same discipline it applied to bolts, brakes, and building materials.
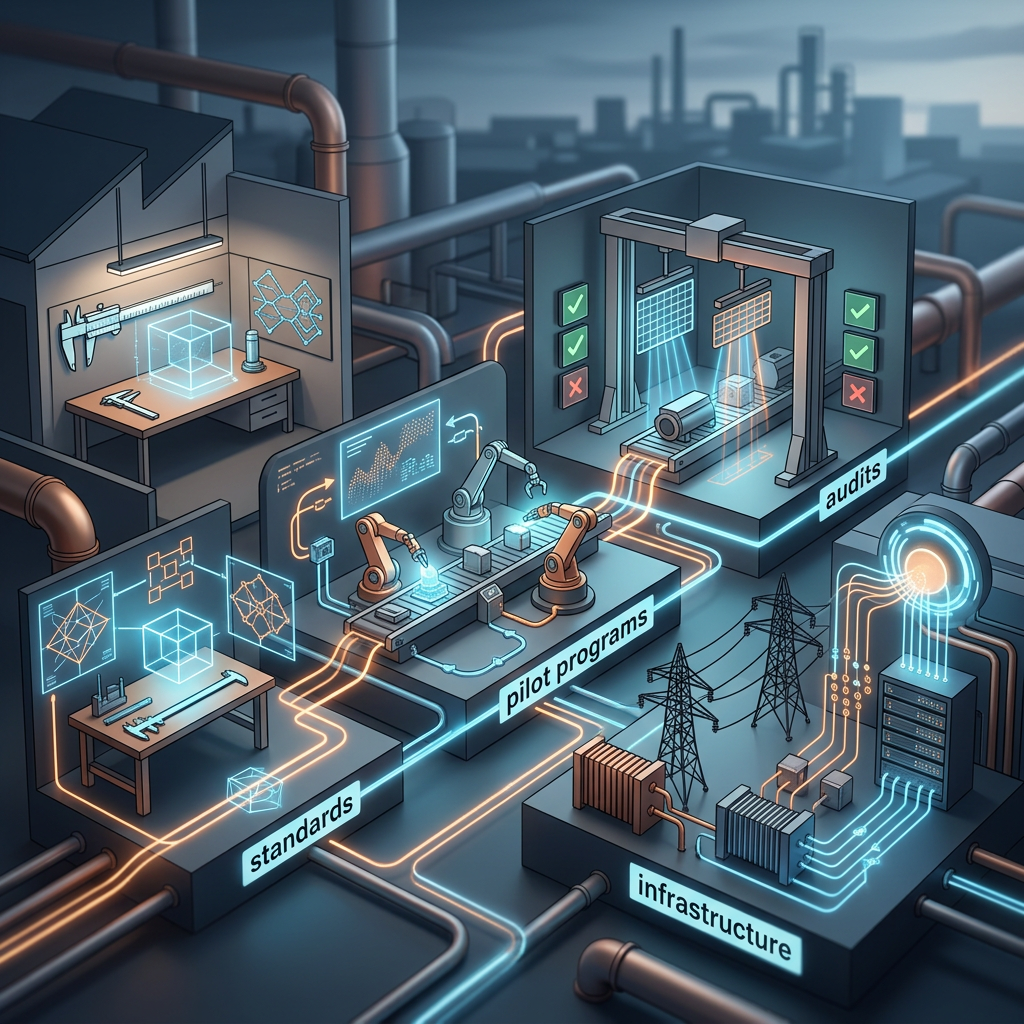
The roadmap is best understood as four interlocking layers: shared standards for measuring judgment and credibility, accredited certification bodies that verify conformance, funded pilot programs that generate real-world data, and continuous audit mechanisms that catch gaming before it corrodes the system. None of these layers requires inventing new institutions from scratch. Each maps onto an existing German competence that simply needs to be extended into a domain — human judgment and predictive track record — that has so far escaped standardization.
Layer One: Extending German Industrial Standards to Judgment
German industrial standards work because they specify requirements precisely enough to be tested. The same logic can be applied to prediction and credibility. The Deutsches Institut für Normung (DIN), which develops and publishes standards across engineering and management fields, is the natural convening body. A working committee on predictive performance could define what a legitimate forecast record actually contains: the claim made, the date it was made, the evidence available at the time, the outcome, and a resolution rule agreed in advance. Without that last element, any track record can be rewritten after the fact.
A second standard would govern self-assessment versus verified assessment. Today, anyone can describe themselves as an accurate forecaster; the equivalent in manufacturing would be a supplier certifying its own tensile-strength tests. German practice separates the claimant from the tester. A DIN-style framework would specify minimum evidence thresholds for different credibility claims — for example, the difference between «has published forecasts» and «has a verified, time-stamped record over a defined period with a stated resolution standard». Crucially, the standard should remain method-agnostic: it defines what counts as proof, not which scoring model is correct, leaving room for competing approaches to prove themselves.
The TÜV organizations offer the template for the verification layer. TÜV SÜD, TÜV Rheinland, and TÜV DEKRA operate as independent technical inspection and certification bodies with decades of experience auditing claims they did not generate. Extending their mandate to credibility certification would mean auditing forecast records, scoring pipelines, and data provenance rather than pressure vessels or vehicle components. This is not hypothetical capability so much as a transfer of existing audit competence to a new object. An auditor who can verify that a weld meets specification can be trained to verify that a prediction log has not been retroactively edited — provided the standard defines precisely what evidence to demand.
Layer Two: Pilot Programs That Generate Evidence
Standards without data are untested hypotheses. Germany’s Mittelstand — the small and medium-sized firms that form the backbone of its industrial base — offers an ideal pilot population. These companies are numerous, regionally concentrated, and already accustomed to certification overhead because their customers demand it. A pilot could run over two or three years in a defined sector, such as machinery or logistics, where forecasts about delivery reliability, maintenance failure, and demand are frequent, time-stamped, and falsifiable. Participants would submit forecasts to an independent registry before outcomes are known, then have their records scored against a published methodology.
| Pilot Component | Design Choice | Purpose |
|---|---|---|
| Scope | One industrial sector, 20–50 firms, 24–36 months | Keeps the dataset tractable and the outcomes comparable |
| Forecast capture | Time-stamped submission to an independent registry before outcome | Prevents retroactive editing and hindsight claims |
| Scoring | Published methodology with pre-agreed resolution rules | Allows third parties to recompute and challenge scores |
| Audit | Independent certification body reviews process, not just results | Tests whether the scoring pipeline itself is trustworthy |
| Publication | Aggregate results and methodology made public | Enables external replication and criticism |
A parallel pilot could run inside the public sector, where the stakes for trust as infrastructure are highest. Procurement agencies routinely make predictions about project timelines and costs that are later verifiable. Recording those forecasts in advance and publishing calibration results would be uncomfortable — which is precisely why it would be persuasive. A public entity that voluntarily submits to forecast scoring signals that credibility is an obligation, not a marketing claim. Sector-specific bodies with existing convening power, such as industry associations and chambers of commerce, could host these pilots without waiting for new legislation.
Layer Three: Audit Mechanisms and the Problem of Gaming
Any metric that acquires economic value will be gamed. This is not a reason to abandon measurement; it is a reason to design for it. The known failure modes are predictable: selective reporting of forecasts, vague predictions that cannot be scored, resolution rules altered after outcomes are known, and scoring systems that reward confidence over calibration. German industrial standards have confronting experience with this dynamic — the diesel emissions testing regime was itself a case study in what happens when verification is too close to the interests being verified, and the subsequent tightening of independent oversight is the relevant lesson.
Designing against gaming
Three safeguards do most of the work. First, pre-registration: forecasts must be logged before outcomes are known, with a hash or timestamp that makes later alteration detectable. Second, pre-committed resolution rules: the method for judging a forecast correct or incorrect must be fixed in advance. Third, separation of functions: the entity that scores must be independent of the entity that audits, and neither should be the entity being scored. Where these three hold, the most damaging gaming tactics become difficult rather than merely discouraged.
Independent auditing is the load-bearing element. It should examine the process rather than merely accepting the output: how forecasts are captured, who can edit records, whether sampling of scored claims is random, and whether the scoring methodology has been changed without disclosure. The physical-testing model is instructive here — an accredited lab is judged on its procedures and its traceability, not only on the certificate it issues. Credibility certification should work the same way. An audited firm should be able to show a prospective client not just its score but the chain of custody behind that score.
Layer Four: From Certification to Infrastructure
Infrastructure, in the sense that matters here, is a system so widely relied upon that its outputs can be assumed rather than re-verified each time. Nobody re-tests the structural steel in a building; the certificate is trusted because the certification system is trusted. The end state for trust as infrastructure is similar: a lending institution, a procurement officer, or an employer encounters a credibility certificate and can treat it as decision-grade evidence, with the same quiet confidence they extend to a calibration certificate for a measuring instrument. That is a higher bar than a score, because it requires the certifying system itself to be audited, funded independently, and governed transparently.
Getting there is incremental. The practical sequence is: a published standard from an established standards body, a pilot in one sector with one independent certifier, public disclosure of methodology and aggregate results, and only then an expansion of scope as evidence accumulates. The German industrial tradition supports exactly this kind of patient, test-driven rollout. The alternative — private scoring platforms that publish methodology when convenient and compete on flattering results — will fill the vacuum if the institutional route stalls. The strategic point for German industry is that credibility certification is a market it is unusually well placed to define and to audit, and that the first movers in that market will set the expectations everyone else is measured against.
Editor verification note: specific named bodies — DIN, TÜV SÜD, TÜV Rheinland, TÜV DEKRA — are referenced as existing institutions whose roles could be extended. Whether any of them has announced work on credibility or forecast certification is not established in the source materials and should be confirmed before publication.
Could Germany Be the First Nation to Treat Credibility as Infrastructure?
The verdict is a measured yes, conditional on execution. Germany is not the only country that could build a credibility infrastructure, but it is one of the few with the institutional raw material to do so at national scale. The same country that gave the world the DIN standard, the TÜV inspection mark, and the dual vocational apprenticeship already treats verifiable performance as public infrastructure. What is missing is the final translation step: extending that machinery from products and skills to judgment itself. If German industry, standards bodies, and policymakers treat trust as infrastructure — designed, certified, audited, and maintained — the country could plausibly become the first nation to do so. If it treats the idea as a communications exercise, the window will close.
Synthesizing the argument of this investigation, three conditions converge in Germany and nowhere else as cleanly. First, the cultural precondition: German industrial success was built on accountability, documentation, and repeatable process, so the idea of scoring judgment objectively is an extension of existing practice rather than a philosophical rupture. Second, the institutional precondition: the country already hosts the certification bodies, audit cultures, and standards-writing communities that a credibility infrastructure would need to operate. Third, the economic precondition: German firms compete on quality signals precisely because they cannot compete on cost, which means they have the most to gain from a credible, portable measure of predictive reliability. Predictive economics is, in this reading, the natural next export category for a nation whose core product has always been dependable expectations.
The condition is execution, and it is demanding. A credibility infrastructure requires neutral governance so that scoring does not become a marketing tool; transparency so that scoring methods can be inspected and contested; and independent audit so that the system’s own performance can be measured against outcomes. It also requires restraint. The moment a credibility score becomes a gatekeeping credential in its own right, it reproduces the very problem it was designed to solve. Germany’s advantage is its familiarity with exactly this tension — the country has spent a century learning how to run standards bodies that resist capture and how to certify without fossilizing. The first nation to treat credibility as infrastructure will not be the one with the most sophisticated algorithm; it will be the one with the most credible referee.
For industry leaders, the practical implication is that waiting is not neutral. Firms that begin piloting objective performance measurement inside controlled settings — internal forecasting leagues, auditable decision logs, third-party review of judgment quality — will accumulate the longitudinal data that later becomes the benchmark. Firms that defer will find themselves measured by frameworks they did not help design. The forward-looking question is not whether credibility will become quantifiable; the evidence points toward partial quantification in specific domains long before any national system exists. The question is who writes the first credible standard, and whether German institutions choose to lead that effort or respond to it.
The one-sentence answer
Germany could become the first nation to treat credibility as infrastructure, because it already treats verifiable performance as infrastructure — but only if it extends its standards, certification, and audit machinery to the measurement of judgment, with neutral governance and public transparency as non-negotiable design rules.
Reader Questions
Three questions surface repeatedly when the case for credibility infrastructure is presented to German industry audiences. They are worth answering directly rather than deferring to later debate.
- Is this simply a rebranding of existing credit ratings and audits? No. Ratings and audits assess balance sheets, processes, and compliance records. A credibility infrastructure assesses the reliability of predictions and judgments before outcomes are known — a different object of measurement requiring different methods and different evidence.
- Does treating trust as infrastructure risk creating a new credential elite? That is the principal design risk, and the reason neutral governance, transparency, and independent audit are treated as preconditions rather than afterthoughts. A credibility system that hardens into a gatekeeping credential would defeat its own purpose.
- What would count as proof that the approach works? The test is outcome validity measured over time: whether objectively scored performance predicts real results better than traditional credentials in comparable settings, documented through independent audit rather than self-reported claims. Any pilot should be designed to make that comparison possible.
The next step for German industry leaders is concrete and modest in scope: commission a single, transparent pilot in one domain, define the outcome metric in advance, submit the methodology to independent review, and publish the results whether or not they flatter the hypothesis. A credibility infrastructure earns its name one audited pilot at a time. Germany has built its industrial reputation on precisely that discipline. The open question now is whether its institutions will apply it to the one asset that increasingly determines national advantage — the measurable reliability of what a country and its companies say will happen next.
Leave a Reply