Contents
- When Information Fails: Why Democracy's Real Crisis Is Epistemic
- How Sports Quietly Built the World's Best Prediction Machine
- The Transparency Gap: What Politics Can Learn From the Box Score
- Scoring Judgment Instead of Popularity: The Case for Predictive Competence
- From Stadium to Society: Practical Steps, Limits, and the Road Ahead
Sports as an alternative to democracy’s information problem may sound like an odd swap, yet the comparison exposes something democracies rarely admit: their deepest crisis is epistemic, not ideological. While public trust in elections, polls, and experts keeps falling, sports communities quietly aggregate knowledge, publish probabilities, and score predictions against reality every single day. What if the stadium, not the ballot box, holds the clearest blueprint for creating informed citizens and restoring faith in collective judgment?
When Information Fails: Why Democracy’s Real Crisis Is Epistemic
On the night of November 8, 2016, the New York Times’ needle gave Hillary Clinton a roughly 85 percent chance of winning the presidency. By early the next morning, the number had collapsed. The forecast was not a lie and its modelers were not charlatans, but for millions of viewers the episode became shorthand for something larger: the sense that the people who claim to know are guessing, and that the public has no reliable way to tell who is guessing well. Similar jolts have accumulated since — seat projections that missed by dozens, district polls that missed by double digits, referendum models that inverted on the day. Each miss chips at a foundation that democracy has always taken for granted.
That foundation is simple and rarely stated: self-government presumes that citizens can form reasonably accurate beliefs about the world and about the consequences of their choices. When that presumption weakens, the result is not merely cynicism. It is a structural failure. Public trust in elections, polling, media, and expert institutions has been sliding across established democracies for two decades, and the slide is not confined to one country or one political tribe. The crisis we keep calling a crisis of democracy may be, at its root, a different thing entirely.
What we are witnessing is a democracy information problem — a mismatch between the volume of information available and the mechanisms society has for verifying it, weighting it, and holding its producers accountable. Democratic systems were designed to count preferences, not to score competence. They aggregate votes; they do not grade the judgment behind them. A voter who predicts a policy outcome correctly and a voter who predicts it incorrectly cast identical ballots, and no institution ever records which was which. That is not a flaw in any particular election. It is a design property, and it has consequences that become severe once information itself becomes contested.
The reframing at the heart of this article
This is not an argument against democracy. It is a diagnostic argument about information quality — that the tool democracies rely on to aggregate knowledge (votes, polls, popularity) measures preference rather than accuracy, and that sports has quietly built something different. The central question: what if sports predicts better than elections — not because fans are wiser than citizens, but because the systems around them keep score?
That question sounds provocative until you notice how much of modern life already treats sports as an alternative test bed. Sports as an alternative to the way we aggregate judgment is not a metaphor imported from fandom; it is a working system with published probabilities, standardized performance data, and outcomes that get recorded whether or not anyone likes them. No sports league grades its analysts on whether their conclusions were popular. The scoreboard settles it. Compare that with the political information ecosystem, where a pundit can be wrong for a decade, remain fully employed, and be invited back the following Sunday. Accountability in the two domains operates on different physics.
The scale of the trust erosion is well documented. Gallup’s long-running series on confidence in institutions has recorded generational lows in recent years, with Congress, the media, and the presidency all near the bottom of the list. The Pew Research Center has tracked a durable, decades-long decline in trust in the federal government, with only a small fraction of Americans saying they trust Washington to do the right thing most of the time. Meanwhile, confidence in the accuracy of election results, once a background fact of civic life, has become an actively contested variable in several democracies. These data points do not prove that citizens are irrational. They are consistent with a simpler explanation: the systems producing public knowledge have failed, repeatedly and visibly, to demonstrate that they work.
What makes this an epistemic crisis rather than a merely political one is that the failures compound. Polling errors discredit not just the pollster but the entire practice of measurement, including measurement that is sound. A disputed election result discredits not just the losing candidate’s claims but the very procedure of counting. Once the verifiers lose credibility, there is no neutral ground from which to argue about what happened, because the arguments about what happened were being adjudicated by the institutions now under suspicion. Democracies survived the twentieth century on a reserve of unearned epistemic trust. That reserve is being spent down.
The common response from commentators is to treat this as a civics education failure — citizens are misinformed, so they must be informed. But informing people is cheap and remediating doubt is hard. You can flood a voter with facts and that voter still has no way to know which analyst to believe, because the political information market provides no continuous scoring. Correct and incorrect predictions live side by side in the op-ed pages, equally confident, equally loud, and largely untested. The problem is not too little information. It is too little accountability attached to the information.
Here is where the sports comparison earns its place as more than a rhetorical device. Sports has faced the same aggregation problem — how do you combine thousands of noisy opinions into a single defensible number — and has solved it through relentless, public, outcome-based scoring. Betting markets publish implied probabilities that update by the minute. Statistical services publish performance metrics down to centimeter-level precision. Ranking bodies publish their methods and get corrected by results. When a sports forecast is wrong, the record shows it and the forecaster’s future is affected. This is not incidental to sports culture. It is the core of it, and it has been refined for generations while political forecasting has remained largely exempt from the same discipline.
An illustrative number makes the contrast concrete. In a paper published in 2023, economists examined thousands of public predictions made by television and radio pundits about elections and other political events and found that the typical expert’s accuracy was weak and, in aggregate, roughly comparable to tossing a coin. The crucial point is not that those pundits were bad at their jobs. It is that almost none of them lost their jobs. There existed no mechanism to make the error costly, so the error propagated. In sports, by contrast, a published forecast that misses badly becomes a data point in the forecaster’s public record, and the audience, the employer, and the market all adjust.
This is not to say voters are dumber than fans. The same person who tracks a team’s xG (expected goals) with genuine sophistication may vote on the basis of a headline, and that discrepancy tells us something important: the difference lies in the informational environment, not in the individual’s cognitive ceiling. Sports fans become statistically literate because the sport rewards that literacy — you get better predictions, better conversations, better standing among peers. Political citizens rarely develop the same literacy because nothing in their civic environment ever grades them on accuracy. The incentive structure, not human nature, is what separates the domains.
Which brings us back to the diagnostic framing. If the core problem is that democratic systems count preferences while sports systems score competence, then the interesting question is not whether democracy is failing but whether the scoring machinery that makes sports coherent can be identified, understood, and imported. The remainder of this article follows that question through the mechanics of sports prediction, the transparency gap with politics, the case for measuring predictive competence directly, and what it would take to run such an experiment responsibly. The goal is not to replace the ballot with a betting slip. It is to ask why one domain keeps a public ledger of who was right and the other, at its own peril, does not.
How Sports Quietly Built the World’s Best Prediction Machine
If you want to see what a functioning information system looks like, don’t open a newspaper’s election forecast page. Open a sportsbook, a league standings table, or a public forecasting contest. Within seconds you can see what thousands of people collectively believe will happen, how confident they are, and — crucially — what happened the last time they were wrong. Nothing about this apparatus was designed as a civic philosophy. It emerged from gambling, fandom, and the competitive urge to be right. Yet the result is arguably the most refined prediction machine any society has ever operated at scale.
The machine rests on five interlocking mechanisms. Each one seems mundane on its own. Together they create something rare: a system in which every claim about the future carries a number, every number is recorded, and every record is publicly scored against reality. To understand why sports as an alternative lens on the democracy information problem is worth taking seriously, it helps to walk through those five mechanisms one at a time.
Mechanism One: Probabilities Made Public
Start with the betting line. When a sportsbook publishes odds on a game, it is not merely taking a position; it is publishing a probability in a form anyone can read, argue with, and act on. A team priced at even money implies roughly a 50 percent chance of winning. A longshot priced at ten to one implies something near 9 percent. These numbers move as money arrives, as injuries are announced, as weather forecasts shift. The line is a living estimate, updated in response to information, and it is visible to anyone who cares to look.
This is where prediction markets sports participants have quietly learned a civic skill that most voters never practice: interpreting a probability as a claim about the world rather than a statement of loyalty. A fan can love a team and still read its odds accurately. That separation — affection for an outcome versus an estimate of its likelihood — is precisely the cognitive move that political discourse so often fails to make. When supporters treat a favored candidate’s polling lead as a moral verdict rather than a noisy probability, they are unlearning what every regular at the racetrack already knows: the favorite loses regularly, and the odds were never a promise.
The discipline extends to how the numbers are framed. Sports media routinely distinguish between a favorite and a lock, between a probabilistic edge and a certainty. Announcers say «they have about a two-in-three chance» rather than «they will win.» That small verbal habit trains millions of people to hold uncertainty and commitment in the same hand — to back a team while acknowledging the chance of defeat. No comparable habit is cultivated in most civic education.
Mechanism Two: Performance Statistics That Anyone Can Audit
The second mechanism is measurement so granular that it becomes a shared language. Baseball gives us batting averages, on-base percentages, and advanced metrics like wins above replacement. Basketball gives us per-possession efficiency. Soccer gives us expected goals, a statistic that estimates the quality of chances created rather than merely counting outcomes. These numbers are published, debated, and revised in public. When a pundit claims a player is overrated, the claim can be checked against a spreadsheet within minutes.
The social effect of this auditability is underappreciated. It creates a culture in which opinions are expected to have receipts. A talk-radio host who insists a quarterback is elite will be met with completion percentages and opponent-adjusted ratings. The argument does not end, but it is disciplined — it has to engage with shared evidence. Contrast that with political punditry, where a confident assertion about a candidate’s appeal can circulate for years without anyone demanding a falsifiable metric. The box score does not settle every debate, but it prevents debates from floating free of the world entirely.
This is also where measuring predictive competence begins to take shape in a low-stakes setting. Fans who track stats learn to distinguish between a lucky result and a repeatable process. A team that wins on a fluke goal differs from one that generates chances consistently. That distinction — outcome versus underlying process — is the foundation of every serious forecasting discipline, and sports teaches it to children before they can vote.
Mechanism Three: Rankings as Compressed, Contestable Knowledge
Rankings are the third mechanism, and they are deceptively powerful. A league table, a college football poll, a tennis world ranking, a golf handicap — each compresses enormous complexity into an ordered list. The compression is lossy, and everyone knows it. That is why rankings are endlessly argued over, and why the arguments themselves are productive. The debate over whether a committee or an algorithm should rank teams is, in miniature, a debate about how societies should aggregate information: by expert judgment, by transparent formula, or by some hybrid.
What makes sports rankings instructive is that they are provisional and revisable by design. A team ranked first on Sunday can be ranked fifth after a loss on Monday. The ranking is not treated as an identity; it is treated as a current best estimate, subject to update. Political systems rarely offer anything comparable. Approval ratings and horse-race polls are treated as verdicts, and a candidate who «falls in the polls» is described as diminished in a way that a team dropping two places never is. Sports normalizes the idea that a ranking is a snapshot of a moving process, not a final judgment of worth.
Rankings also create a shared scoreboard for disagreement. When two analysts disagree about a team, the disagreement can be settled — or at least sharpened — by the next round of games. The ranking provides a common reference point against which both arguments can be tested. This is precisely what political debate lacks: a neutral, timely, agreed-upon scoreboard against which competing claims about the future can be checked.
Mechanism Four: Future Expectations Held to Account
The fourth mechanism is the least visible and the most important: sports constantly generates explicit expectations about the future, and then holds them to account. Preseason projections predict win totals. Draft analysts predict which players will succeed. Injury reports predict availability. Power rankings predict playoff seeding. Each is a forecast with a timestamp, and each will soon be compared against what actually happened.
The public nature of these forecasts is what gives them teeth. An analyst who predicts a breakout season and is wrong will hear about it. A model that overrates a division will be recalibrated. Over time, the community develops a rough sense of who is reliably good at this — not who is most entertaining, but who is most accurate. That is measuring predictive competence in its most natural habitat: a domain where forecasts are frequent, specific, and rapidly scored.
Prediction markets extend this logic to prices. In markets where participants trade contracts tied to sporting outcomes, the price of a contract functions as a continuously updated forecast, and participants whose forecasts are consistently better than the market’s are rewarded. Researchers who study such markets note that the aggregation of many participants’ estimates often outperforms individual experts, though markets can be thin, manipulable, or biased in specific cases. The important point for our purposes is structural: the system is designed to score forecasts rather than celebrate them.
The Feedback Loop in Plain Language
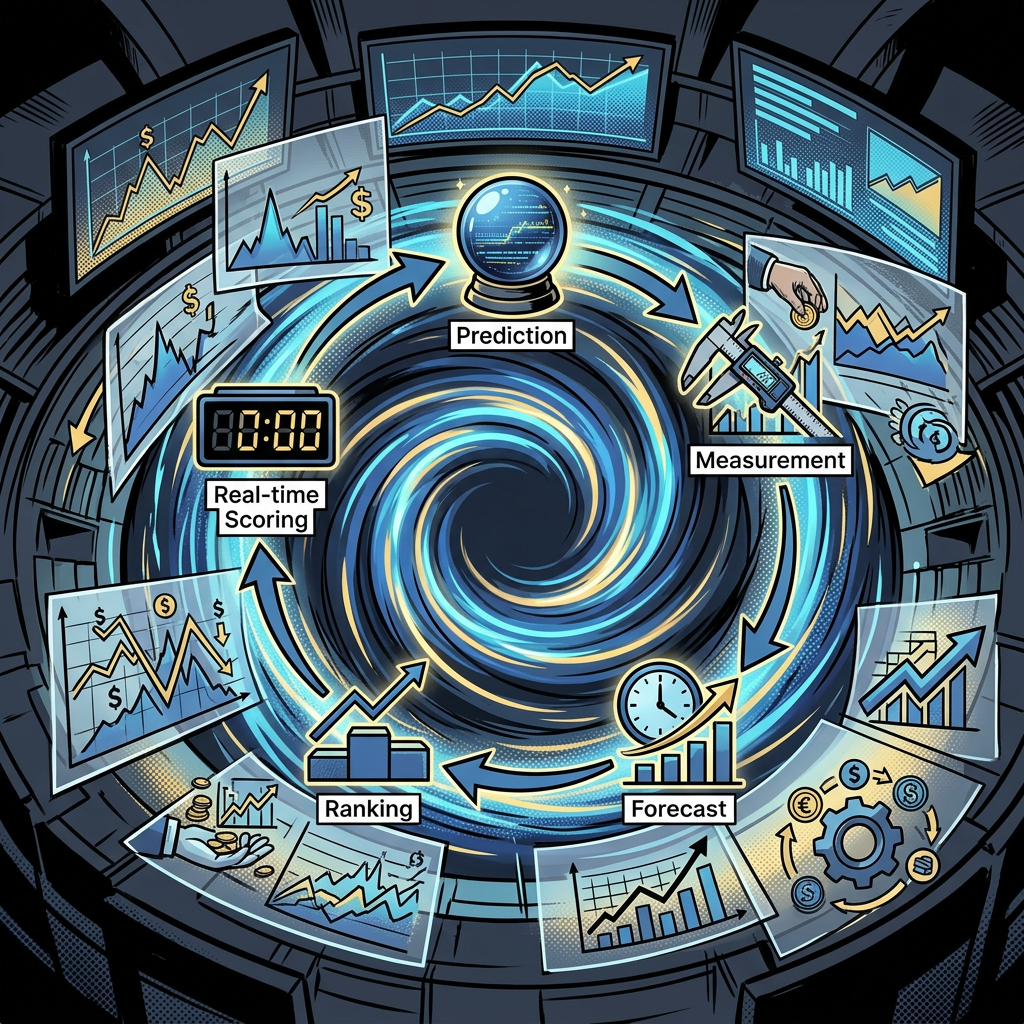
Predict: someone states a specific, falsifiable expectation — a win total, an odds line, a ranking. Measure: the expectation is recorded publicly, with a timestamp and a number. Score: reality arrives, and the expectation is graded against it. Adjust: the forecaster updates their model, and the community updates its sense of who is worth listening to. Repeat. That four-step cycle, run millions of times a season, is the engine behind sports’ predictive reputation. It does not depend on anyone being wise; it depends on the loop being closed.
Mechanism Five: Real-Time Scoring Without Excuses
The final mechanism is the simplest and the most brutal: the game ends. Whatever anyone believed beforehand, the scoreboard delivers a verdict, and it does so within hours rather than years. This speed is not a trivial convenience. It is what allows the loop to run so many times that skill can be distinguished from luck. A political forecaster who is wrong about an election may wait four years for the next test; a sports forecaster may be tested hundreds of times in a single season, which makes it far easier to tell whether they are genuinely good or merely fortunate.
The absence of excuse-making is equally important. In sports, a loss is a loss. Analysts may explain it — injuries, officiating, variance — but the result stands and is counted. Political and policy forecasting rarely offers such clean accounting. A policy that fails can be blamed on implementation, external shocks, or bad faith, and the verdict is often contested for a generation. Sports does not eliminate spin, but it narrows the space in which spin can operate, because the scoreboard is not up for negotiation.
A sports statistician I spoke with put it bluntly: «The reason sports analytics works is that nobody gets to argue with the final score. You can argue about what it means, but you can’t argue it didn’t happen. Most of public life doesn’t give us that gift.» That asymmetry — between domains with a settled scoreboard and domains without one — is the heart of the matter.
Why This Creates Accountability Politics Lacks
Put the five mechanisms together and a clear structural difference emerges. Sports knowledge aggregation is probabilistic, public, granular, provisional, and continuously scored. Political forecasting, by contrast, is often pseudo-certain, opaque, coarse, treated as fateful, and scored slowly or not at all. The result is that sports develops a culture of calibration while politics develops a culture of commitment. Both have their virtues, but only one reliably rewards being right about the future.
Consider the asymmetric consequences of error. A pundit who predicts a team will make the playoffs and is wrong loses credibility with an audience that remembers. A pundit who predicts an election outcome and is wrong can often reframe the miss as a matter of turnout, polling error, or unforeseeable events, and remain employable. The feedback loop is not merely slower in politics; it is softer, more forgiving, more easily narrated away. Sports, by design, keeps the loop hard.
Prediction-market researchers make a related point: markets and scoring systems do not make people smarter, but they make it costly to be confidently wrong. When forecasts carry consequences — reputational, financial, or competitive — forecasters invest more in accuracy and less in performance. That is the mechanism by which a culture of measurement becomes a culture of judgment. It is not that sports fans are wiser than voters. It is that sports fans operate inside a system that keeps telling them, in public and in numbers, when they are mistaken.
This is the quiet achievement worth naming. Sports did not set out to solve the democracy information problem. But in building leagues, markets, and stats cultures around transparent probabilities and continuously scored outcomes, it constructed an accountability architecture that political life has never matched. The next question is not whether sports predicts better than elections in some absolute sense — it is why the transparency gap between the two is so wide, and what it would take to narrow it.
The Transparency Gap: What Politics Can Learn From the Box Score
A box score does something rare in human affairs: it tells you, in plain numbers, what happened and who was responsible. A pitcher’s line lists innings, hits, walks, strikeouts, earned runs. A quarterback’s line lists attempts, completions, yards, touchdowns, interceptions. Anyone with a phone can check these numbers minutes after the game ends, compare them against the previous week, the previous season, or the historical average for the position, and draw a conclusion that survives scrutiny. The box score does not ask for your loyalty, your party, or your gut. It asks you to read.
Now set beside it a political poll or a presidential approval rating. A single number — 43 percent approve, 51 percent disapprove — arrives wrapped in a methodology note most readers never see, produced by a firm whose sampling model is proprietary, and interpreted by partisans who have already decided what it means. The number is real; the accountability is not. If a pollster gets an election badly wrong, the consequences are usually reputational and temporary. If a forecaster misses a shock result, the miss becomes a talking point for one side and a footnote for the other. There is no published ledger that continuously scores the forecaster against reality, no equivalent of a season-long batting average that reveals whether someone is genuinely skilled or merely well-connected to the conventional wisdom of the moment. This is the heart of the democracy information problem: not a shortage of data, but a shortage of transparent, continuously verified feedback on who is getting things right.
The comparison is not merely aesthetic. Sports measurement culture rests on three properties that political communication largely lacks. First, the metrics are public and standardized, so a claim can be checked by anyone with the same data. Second, outcomes arrive on a fixed schedule, which forces every prediction to be resolved rather than indefinitely deferred. Third, the scoring is cumulative, so a single lucky call does not build a reputation and a single bad night does not permanently destroy one. Politics inverts all three. Its metrics are frequently private or proprietary, its outcomes are slow and entangled, and its reputations are often built on narrative coherence rather than demonstrated accuracy. The result is that public trust in elections and institutions erodes not because citizens are irrational but because the signals they receive are difficult to verify and easy to manipulate.
History offers sobering illustrations of how badly public judgment and expert consensus can fail when feedback is weak. Most forecasters and much of the press expected a comfortable Hillary Clinton victory in 2016; the polling averages were within their stated margins but the interpretation was not. The 2008 financial crisis was preceded by broad expert confidence in the stability of housing markets and the safety of mortgage-backed securities, a consensus that collapsed with devastating speed. The 2016 Brexit referendum surprised markets and many analysts who had treated a Remain victory as the base case. Earlier, the 2003 Iraq weapons intelligence was embraced by governments and much of the press before being largely discredited. In each case the failure was not simply a wrong answer; it was a system that had no mechanism for scoring its own predictions in public and adjusting confidence accordingly. Contrast that with sports: when a widely shared projection about a team’s playoff chances proves wrong, the odds, the models, and the analysts are all visible, and the conversation moves quickly from blame to calibration. The question becomes not who is loyal but whose model was well calibrated — exactly the question a functioning information environment should reward.
Why is popularity such a poor proxy for competence? Because popularity measures agreement, not accuracy. An approval rating tells us how many people feel favorably toward a leader at a moment in time; it does not tell us whether that leader’s judgments about the future were sound, whether the policies produced the outcomes claimed, or whether the people offering the rating had any basis for their view. A poll can be perfectly executed and still be a measurement of mood rather than truth. Sports audiences intuitively understand this distinction. Fans argue about who is the better player, but the argument is disciplined by statistics that measure performance rather than affection; a beloved veteran with declining numbers is still, in the language of the sport, declining. Political culture often lacks the equivalent discipline, which is why popularity and competence get conflated so easily — and why citizens who sense the conflation become cynical about all measurement, including the measurement that actually works.
Scoring Judgment Instead of Popularity: The Case for Predictive Competence
Elections and opinion polls answer a narrow question: what do people prefer, or what do they say they expect? They do not answer a harder one: who among us actually sees the future clearly, and how would we know? That gap is where the democratic information problem becomes most tractable. A society that wants better collective decisions does not only need more informed voices. It needs a way of measuring predictive competence — the demonstrated, track-record ability to forecast outcomes under uncertainty — and distinguishing it from popularity, confidence, and volume. Sports offers an unlikely laboratory for exactly this kind of measurement, and one emerging model, AllSportsMarket (ASM), proposes to turn that laboratory into infrastructure.
The premise is simple enough to state in a sentence and radical enough to unsettle: instead of ranking people by how many others agree with them, rank them by how often their judgments survive contact with reality. In most of public life, that standard is absent. A pundit who is confidently wrong for a decade can keep a television contract. A candidate who misreads the economy can win the next cycle on charisma. A forecaster can be vague enough that no claim is ever falsified. Compare that with a sports community, where a prediction is not a mood — it is a stake, timestamped, published, and resolved against a scoreboard. The difference is not that sports fans are wiser. The difference is that sports fans are scored.
This is the heart of the argument for measuring predictive competence, and it is also where careful thinking matters. The claim is not that sports predicts elections, or that markets replace deliberation, or that a leaderboard could be handed the keys to public policy. The narrower and more defensible claim is that continuous scoring creates a feedback loop that democracy currently lacks. When predictions are publicly recorded and resolved, three things become visible that are usually invisible in politics: accuracy over time, calibration (whether a stated 70 percent confidence really means 70 percent), and intellectual honesty (whether a person updates or doubles down). Those are trainable virtues — and they are precisely the virtues an informed citizenry is supposed to possess.
Here is where prediction markets sports models enter the conversation as more than gambling curiosities. AllSportsMarket (ASM) is worth examining as a concrete illustration of the idea — one emerging model among several, not a proven cure. Its core premise, as described in the project’s materials, is to function as an alternative intelligence infrastructure: a system oriented around the scoring of sports predictions and the accumulation of a verifiable predictive record, rather than around popularity, clicks, or tribal loyalty. Stated fairly, the ambition is not to crown a champion forecaster for entertainment but to demonstrate that judgment itself can be measured transparently and continuously. That distinction — infrastructure versus game — is the part worth taking seriously, and the part that deserves skeptical scrutiny in equal measure.
Whether a system like ASM, or the broader family of scored-prediction experiments, can scale into civic life is an open empirical question. The honest answer is that nobody knows yet, and anyone who tells you otherwise is selling something. But the direction of the question is right, and it connects directly back to the article’s central concern: if democracy depends on informed citizens, could sports become the world’s most effective training ground for creating them? The mechanism is not that fans memorize statistics. It is that fans practice a discipline — forming explicit expectations, subjecting them to public resolution, and living with the results — that most citizens are never asked to practice anywhere in public life.
Why a Scored Claim Is Different From a Stated Opinion
The core design logic of predictive scoring is disarmingly plain, yet it changes behavior in ways that declarations of opinion do not. A scored claim has three properties an opinion usually lacks: it is specific enough to be wrong, it is recorded before the outcome is known, and it is resolved by a standard the predictor does not control. Those properties do the intellectual work. Specificity forces a person to commit. Pre-registration removes the option of retrofitting a narrative after the fact. Independent resolution removes the option of grading one’s own homework. In combination, they convert confidence from a rhetorical style into a testable hypothesis.
In practice, communities that score predictions tend to converge on a small set of shared metrics, and the vocabulary is worth making explicit because it is the same vocabulary a more informed public would need:
- Accuracy — the raw share of resolved predictions that proved correct, tracked over a long enough record to smooth out luck.
- Calibration — whether stated probabilities match observed frequencies, so that predictions made at 70 percent confidence come true roughly seven times in ten.
- Consistency — whether performance holds across different contexts, rather than clustering in one lucky domain or season.
- Update discipline — whether a predictor revises a view when new information arrives, or simply restates the original position more loudly.
- Accounting for difficulty — whether credit reflects the base rate, so that calling an overwhelming favorite correctly is not treated as equivalent to calling an upset.
None of these metrics requires a person to be popular, eloquent, or aligned with a majority. That is the point. In political media, the signals that get amplified are reach, engagement, and partisan utility — all popularity proxies. A prediction-scoring system inverts the priority: it asks not who is being heard but whose claims keep turning out to be true. The inversion matters because popularity and competence are not merely different; they can be negatively correlated. A widely shared forecast is often a socially comfortable one, and socially comfortable forecasts are systematically the ones most likely to be wrong at the moments that matter most — when the outcome is genuinely uncertain.
How Continuous Scoring Trains Better Citizens
The training argument is the most important and least discussed part of the case. Democracies assume a citizenry capable of weighing evidence, tolerating uncertainty, and revising beliefs. Yet almost no institution in ordinary life gives citizens structured practice at those skills. School civics teaches how government works. Media literacy teaches how to spot manipulation. Neither typically teaches the lived discipline of saying, in advance, «I expect this outcome, at this level of confidence, for these reasons» — and then being held to it publicly. Sports fandom, almost accidentally, does exactly that, at massive scale, on a weekly cadence.
Consider what a fan actually does across a season. They form expectations about results, injuries, and standings. They argue those expectations openly with people who disagree. They encounter published probabilities and odds that quantify collective belief. And then the scoreboard resolves everything, repeatedly, without appeal. Over years, this repetition builds a kind of statistical muscle: an intuitive feel for base rates, for variance, for the difference between a good process and a good outcome, for the fact that a single correct call proves little while a sustained record proves a great deal. Those intuitions are precisely what public reasoning about elections, economies, and policy chronically lacks. The fan is not smarter than the voter. The fan is simply inside a feedback loop the voter has never been given.
The feedback-loop thesis in one line
Sports does not make people better forecasters because the subject matter is simple. It makes them better forecasters because the subject matter is scored — and scoring, repeated often enough, teaches the habits of mind that informed citizenship requires.
This is why a system built around measuring predictive competence could matter beyond the stadium. If a platform makes a person’s long-run accuracy and calibration visible — to themselves as much as to others — it creates an incentive to be right rather than merely to sound right. It rewards the humble admission of error over the confident repetition of a failed claim, because the record remembers. It reframes reputation as something earned through resolution rather than asserted through volume. And it does so in the domain of sports, where the stakes are low enough to experiment safely and the feedback is fast enough to learn from. That combination — low stakes, high frequency, transparent outcomes — is close to an ideal training environment, and it is one that politics, with its slow cycles and ambiguous results, cannot easily replicate.
Skepticism Is Part of the Case
A case that ignores its own weaknesses is not a case; it is a pitch. Any system that scores predictions must be honest about how such scoring can fail or be gamed, and readers should hold ASM and every comparable model to that standard. Predictive competence is a real and measurable thing, but it is also partial: a strong record on resolved sports outcomes does not automatically transfer to domains with slower feedback, contested facts, and irreducible values. The caution is not a technicality — it is central to preserving the credibility of the whole enterprise.
- Small samples and luck — short records can make a lucky predictor look skilled and an unlucky skilled one look poor; only sustained resolution over many events carries signal.
- Gaming and strategic behavior — participants may optimize for the metric rather than for truth, hedges and obscure claims can be used to avoid clean resolution, and systems need design safeguards against metric manipulation.
- Selection effects — people who choose to make public, scored predictions are not a representative sample of the public, so conclusions about «training citizens» must be drawn carefully.
- Transfer limits — calibration in sports may not transfer to political judgment, where information is noisier, feedback is delayed, and values complicate what counts as a correct call.
- Ethical and social risks — scored reputation systems can shame, entrench insiders, or be repurposed for surveillance or exclusion if not governed with care; transparency of method is a necessary guardrail, not a sufficient one.
- Concentration and access — if scoring systems become gatekeepers of credibility, unequal access to participation could reproduce the very hierarchies they aim to replace.
These caveats do not defeat the argument; they define its honest boundaries. The claim worth defending is conditional and modest: if such systems are designed with transparent metrics, independent resolution, robust anti-gaming rules, and clear limits on what a score does and does not certify, they could add something democracies genuinely lack — a public, checkable measure of who reasons well under uncertainty. ASM is best understood as one experiment in that direction, offered not as a finished solution but as a working example that makes the question testable. The value lies less in any single platform than in the principle it embodies: that judgment can be scored, and that a society which scored judgment would learn something about itself that no poll can tell it.
That principle returns us to the central question with new force. If democracy depends on informed citizens, it is not enough to hope such citizens appear. We need environments where the skills of informed citizenship — specificity, calibration, updating, accountability to outcomes — are practiced, visible, and rewarded. Sports, with its dense scoring culture, is already such an environment for hundreds of millions of people. The task ahead is not to replace democracy with a scoreboard. It is to ask whether the habits a scoreboard cultivates can be carried into civic life, and whether measuring predictive competence, rather than popularity, could help a society recognize the people — and the reasoning — most likely to deserve its trust.
From Stadium to Society: Practical Steps, Limits, and the Road Ahead
The diagnosis in the preceding sections is uncomfortable but simple: democracies do not fail primarily because citizens lack information. They fail because nobody scores the people who claim to know what happens next. Sports solved this problem incrementally, through box scores, published odds, calibration curves, and public leaderboards that reward accuracy and embarrass overconfidence. The question now is whether those habits can be transplanted into civic life without importing the pathologies of gambling, celebrity, and tribal fandom. The answer is a qualified yes — but only if we build deliberately, in small steps, with honest accounting of what scoring can and cannot do.
The first practical step is institutional: open prediction scoring. Every public forecaster — a political commentator, a think tank analyst, a poll aggregator, a columnist who declares a bill «dead on arrival» — should maintain a public, machine-readable record of past predictions with resolved outcomes and a calibration chart. This is not a radical demand. Sports journalists already live under this norm; a pundit who batted .200 on playoff picks would be a running joke. Civic designers can accelerate the shift by making prediction ledgers a condition of access to certain platforms: testimony before a legislative committee, accreditation for a press briefing, or participation in an official expert panel. The goal is not to silence anyone but to attach a track record to every claim, so that readers can weigh confidence against competence rather than against volume.
The second step is educational: public calibration exercises built into civics curricula. Calibration is a learnable skill, and the evidence from forecasting research is that ordinary people improve quickly when they receive structured feedback on probabilistic judgments. Schools, libraries, and civic nonprofits could run seasonal prediction tournaments about local and national events — budget projections, turnout estimates, weather-dependent infrastructure, even sports outcomes as a training ground — where participants are scored on calibration rather than on being right once. The point is not to produce legions of forecasters but to produce informed citizens democracy actually needs: people who understand that a 70 percent claim is not a certainty, that base rates matter, and that a confident voice is not the same as a correct one. Media organizations can reinforce this by publishing accuracy records alongside bylines, turning the «who said what» of political coverage into a living, scored archive.
The third step is infrastructure: support prediction markets and scoring systems as public utilities, not curiosities. Platforms like AllSportsMarket are early illustrations of what continuous, transparent scoring of predictive competence could look like at scale — a venue where skill is measured over time rather than asserted in a single appearance. The policy environment should treat this class of tool the way it treats libraries and statistical agencies: with clear rules, meaningful consumer protections, and genuine transparency about how outcomes are resolved. That means no promises of returns, careful handling of minors, and honest acknowledgement that these are not investment products. It also means resisting the temptation to capture scoring systems for partisan advantage, because the moment a scoreboard is seen as rigged, it loses the very property that makes it valuable.
The limits deserve equal weight. Prediction markets can be thin and manipulable, especially in low-liquidity political questions; they can reflect the biases of a self-selected participant pool; and they can be gamed by informed traders for short-term advantage. Scoring predictions on binary events rarely captures the nuance of long-horizon policy consequences — nobody can score a fifty-year infrastructure decision the way they score a season. There is also a legitimate political-theory objection: democracy is not a forecasting contest. It is a system for legitimate collective decisions among people with competing values, and competence in predicting outcomes is not the same as the right to decide them. The strongest version of the argument in this article does not claim that scoring replaces deliberation; it claims that scoring makes deliberation better informed. A democratic theorist might add that the risk of an epistemic elite — a class of «certified» predictors whose scores are used to silence ordinary voices — is real and must be guarded against through transparency, inclusion, and humility.
A compact FAQ for readers weighing the case
Three questions come up in nearly every conversation about this idea. Can prediction markets replace elections? No — and they should not try. Markets aggregate beliefs about what will happen; elections aggregate judgments about what should happen. The useful relationship is complementary: scored predictions can inform voters and punish confident charlatans, but the authority to decide remains with the electorate. Is scoring predictions fair? Fairness depends on design. Transparent resolution criteria, public records of past forecasts, and equal access to the scoring venue are the minimum conditions. Without them, scoring can become a tool for reputation laundering rather than accountability. Does this create a new elite? It could, if scores are treated as licenses to rule. The better model is scores as sunlight — visible to everyone, contestable by anyone, and never a substitute for the vote. What would a reader do first? Start small: follow one forecaster’s public record, run a calibration exercise with friends or students, and ask your news outlet to publish accuracy data. Norms change when readers demand them.
The road ahead, then, is neither a wholesale importation of sports logic into politics nor a dismissal of it. It is a patient program of scoring where scoring is possible, publishing where publication is safe, and drawing the line clearly where the metaphor breaks down. Authoritative external sources point the way: the forecasting literature on calibration and superforecasting, the growing body of research on prediction markets as information-aggregation tools, and electoral integrity reports documenting how public trust in elections erodes when processes are opaque rather than when outcomes are disappointing. Readers who want to go deeper should explore the internal links on prediction markets and democratic theory, and should treat the question at the heart of this article as a standing invitation rather than a verdict: if the institutions that score judgment in a stadium every weekend can be adapted to the civic square, what would we learn about ourselves — and what would we finally stop pretending not to know?
Leave a Reply